Context Engineering
Context engineering treats a model's working set as a designed runtime system, selecting instructions, data, tools, history, and constraints for a bounded, observable decision.
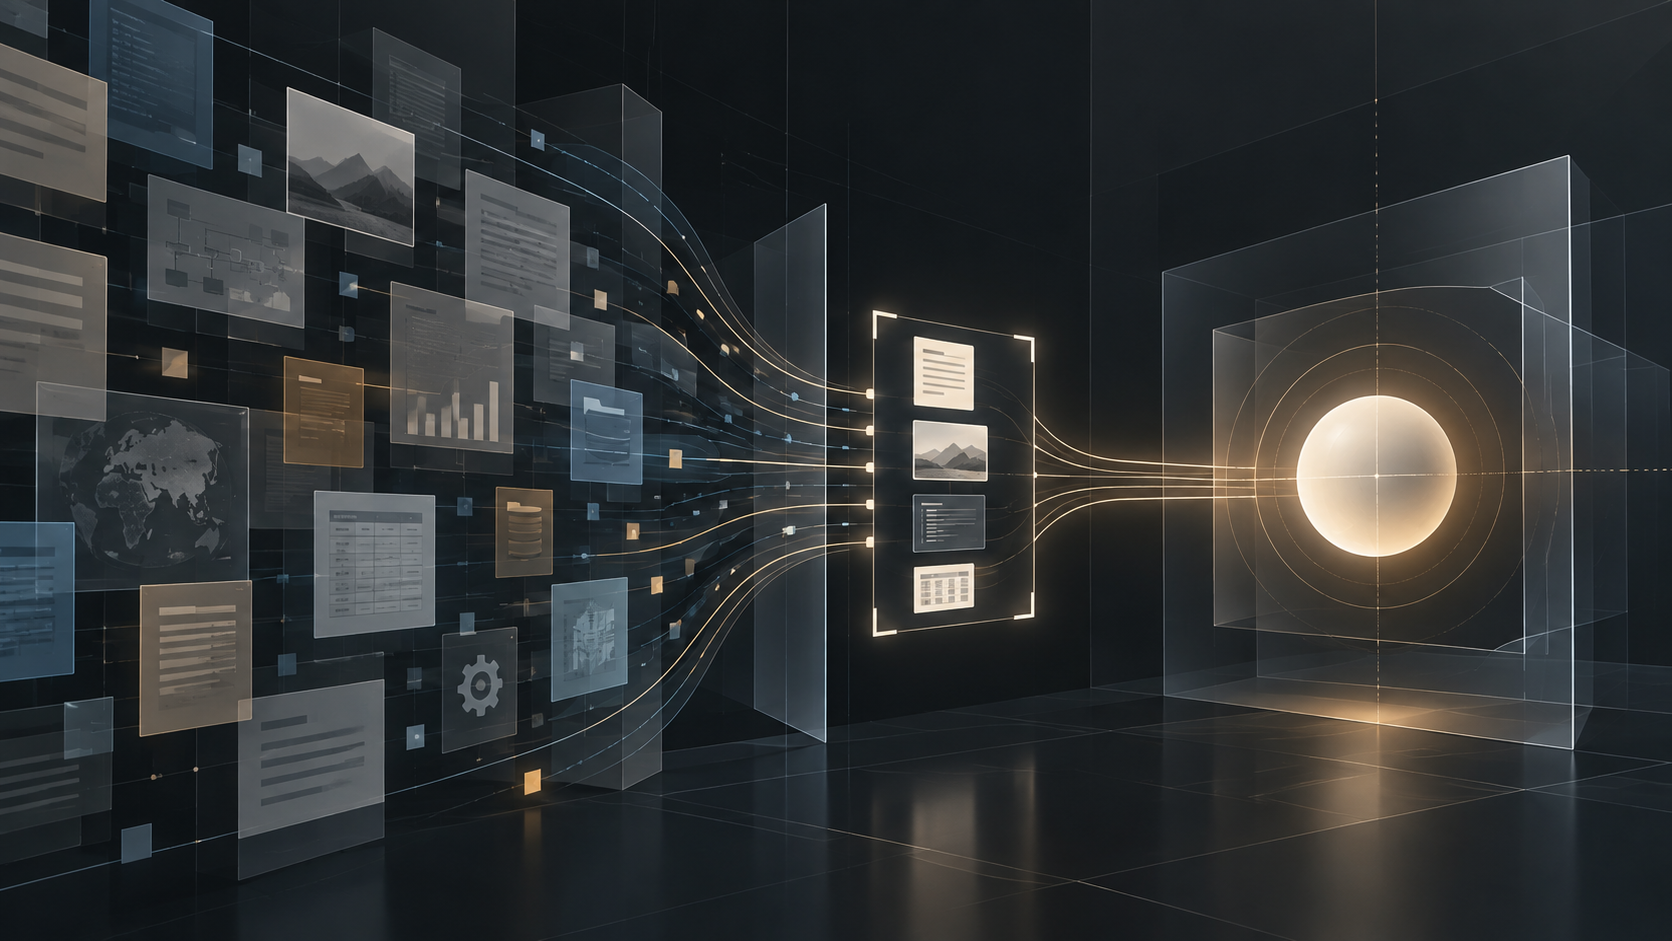
Context Engineering
When Prompting Became Systems Engineering
The hard part of an AI application is rarely finding one more clever sentence for its prompt. The harder problem is deciding what the model should be allowed to see at the exact moment it must make a decision.
That decision may depend on the user’s request, system instructions, a few examples, recent conversation, retrieved documents, tool definitions, tool results, application state, identity, policy, and the outcome of earlier steps. All of those inputs compete for a limited working set. Some are authoritative. Some are stale. Some are untrusted. Some are useful only if the model asks for them at the right time.
This is the problem now commonly called context engineering.
Context engineering is not a replacement for prompting. It is the larger systems problem that appears when a prompt becomes one component of a runtime-managed context. The durable question is not how to put more text in front of a model. It is how to assemble the smallest useful working set, preserve its meaning and authority, and observe what the model actually received.
This is Post 06 in The Abstraction Shift: How Software Keeps Moving Up.
Why This Exists
A one-shot model call encourages a simple mental model:
user request + prompt
          |
          v
        model
          |
          v
        answer
That model is useful for a narrow task. It becomes incomplete when the application can search, inspect files, call APIs, remember earlier work, or delegate to another process.
The possible information available to the system is much larger than the information sent to the model:
enterprise data, documents, tools, history, state, policy
                         |
                         v
              context selection and assembly
                         |
                         v
                model-facing working set
The system therefore has two different spaces:
- The information space, which contains everything the application could retrieve, calculate, or expose.
- The context space, which contains the selected material included in the next model input.
The model does not reason over the whole information space. It reasons over the context it receives, plus whatever it can obtain through the capabilities made available to it. An important architectural consequence follows:
If a fact is not in the current context and the model has no reliable way to obtain it, that fact is effectively absent from the decision.
This is why a retrieval system, an MCP server, a memory store, or a tool catalogue does not automatically become useful context. Availability is not selection. Selection is not trust. Trust is not authority.
As AI applications moved from single-turn generation toward agents and longer workflows, engineers needed a name for the broader work of managing this changing working set. Anthropic describes context engineering as the curation and maintenance of the tokens available to an agent during inference, including system instructions, tools, protocol information, external data, and message history. The term is useful because it makes the runtime context a design object rather than an accidental concatenation of strings.
What We Did Before
Software engineers have always assembled working inputs for computation. The names were different because the caller and the computation behaved differently.
Configuration and dependency injection
An application starts with configuration, credentials, feature flags, environment variables, and dependencies. The runtime assembles those values before a component executes.
This is a useful analogy for context engineering because it makes assembly and ownership visible. It is incomplete because a model does not reliably interpret every configuration value as a deterministic parameter. It may misunderstand a value, give too much weight to a less authoritative instruction, or act on content that was never intended to control behavior.
Request context
Web frameworks and service runtimes carry request context: identity, locale, correlation identifiers, deadlines, cancellation state, and tracing information. A handler receives only the context relevant to that request.
This is closer to the runtime problem. Context is scoped, assembled, and propagated. But model-facing context usually mixes operational metadata with natural language, examples, documents, and proposed actions. The result is not a typed call frame unless the application makes it one.
Working sets and caches
Operating systems and databases avoid treating all available data as equally active. They maintain a working set of information likely to be needed soon and move information in and out as access patterns change.
The analogy helps explain why more context can make a system worse. It breaks when tokens are mistaken for addressable memory. A model does not perform a deterministic lookup against a token list. Position, wording, repetition, ambiguity, and relationships between items affect how the input is interpreted.
Retrieval pipelines
Search systems retrieve candidate records, rank them, and return a limited result set. Retrieval-augmented generation extended that pattern by placing selected records beside a user’s request before generation.
Context engineering includes retrieval, but it is broader. It also governs instructions, examples, tools, history, identity, policy, observations, and the decision to retrieve more information later. Retrieval is one source of context, not the whole context architecture.
Prompt templates
Prompt templates made a model call repeatable. They separated stable instructions from changing values and allowed teams to test variants.
That remains valuable. The shift is that the changing values are no longer only form fields or database rows. They can include a model-selected tool, an observation from the last step, a retrieved document, a summary of an earlier context window, or a policy decision. The template has become a runtime assembly boundary.
What’s Actually New?
Several parts of this practice have familiar relatives. The combination creates a different engineering boundary.
The model becomes a consumer of a designed working set
Traditional software also consumes configuration, data, and state. The difference is that a model can interpret the combined natural-language and structured input semantically and use that interpretation to choose what happens next.
The system must therefore design not only the values it provides, but also their framing, order, scope, provenance, and relationship to other values.
Relevance becomes an operating concern
In a deterministic query, a missing row, a wrong filter, or a malformed parameter can often be detected through explicit checks. In a model context, an item can be technically present and still fail to influence the result, or influence the result in an unintended way.
Context quality has at least four dimensions:
- Relevance: Is this useful for the current decision?
- Authority: Is this allowed to define what the system should do?
- Freshness: Is it current enough for the decision?
- Legibility: Can the model and the runtime distinguish it from surrounding material?
These dimensions are not interchangeable. A highly relevant document can be untrusted. An authoritative policy can be stale. Fresh telemetry can be difficult to interpret without a schema. A useful tool result can be too large to fit into the next decision.
Context is a control surface
Context does not only provide facts. Instructions, tool descriptions, examples, retrieved content, and previous observations can influence which operation the model proposes next.
That makes context part of the control surface of the application. A retrieved document may contain an instruction that attempts to redirect the model. A tool result may include data that looks like a policy. A stale example may teach behavior the current system no longer permits.
The system must distinguish information that should be considered from instructions that should be obeyed. That distinction cannot be delegated to the model alone when the model can affect external systems.
Context becomes a lifecycle
In an agent loop, context is assembled repeatedly:
goal
  -> context
  -> model proposal
  -> tool or human observation
  -> updated context
  -> next proposal
The context is therefore not a static prompt. It is a projection that changes as the system learns, acts, summarizes, retrieves, fails, and recovers. The lifecycle needs ownership, versioning, expiration, compaction, and auditability.
Limits become part of the architecture
Context has a finite window, a cost, a latency, and a quality curve. More available space does not remove the need for selection. Research on long-context behavior has shown that relevant information can be used less reliably when it is buried among large amounts of other material. Anthropic calls the resulting degradation context rot.
The durable engineering response is not to assume that a larger window solves the problem. It is to treat context as a budget and to test how the system behaves when relevant information is moved, omitted, summarized, duplicated, or contradicted.
Where the Analogy Breaks
Historical analogies make the topic accessible, but each one fails at a different boundary.
| Analogy | What it explains | Where it breaks |
|---|---|---|
| Configuration | Inputs can be assembled before execution | Model interpretation is probabilistic, and natural-language values can compete with one another |
| Working set | Only a subset of available information should be active | Tokens are not addressable memory, and attention is not deterministic lookup |
| Retrieval pipeline | Candidate information can be found and ranked | Context includes instructions, tools, state, identity, and observations, not only documents |
| Application state | The system carries information across steps | Model-facing context is a projection, not the authoritative source of truth |
| Compiler | A runtime can transform inputs into an execution representation | Equal context does not guarantee equal behavior, and the model is not a deterministic target language |
| Conversation history | Earlier turns can preserve continuity | History accumulates noise, stale assumptions, secrets, and untrusted instructions |
The important break is this:
Context is not truth, memory, permission, or a complete description of the world. It is a deliberately constructed view of what a model may consider for one decision.
The application must keep authority elsewhere. The model can interpret the projection and propose a next step. Deterministic systems must still own validation, authorization, execution, persistence, and outcome reporting.
Under the Hood
A useful context architecture separates the world of possible inputs from the projection sent to the model.
1. Establish scope
Start with the task, user identity, tenant, permissions, deadline, risk level, and required outcome. The same question can require different context for different users or actions.
2. Gather candidates
Collect only from owned and observable sources: authoritative records, approved retrieval indexes, tool descriptions, current state, prior observations, and explicit user input. Keep stable identifiers for large objects so the system can load details progressively.
3. Filter and rank
Apply deterministic scope, policy, data-classification, freshness, and size filters before semantic ranking. Relevance should not override authorization. A document should not enter context merely because it matches the words in the question.
4. Annotate meaning
Preserve source, owner, timestamp, freshness, scope, confidence, and trust classification. If two sources disagree, make the disagreement legible rather than silently merging them into one fluent paragraph.
5. Allocate the budget
Reserve space for the user’s goal, required instructions, tool schemas, evidence, observations, and the expected response or next action. Do not spend the entire budget on retrieved material and leave no room for the model to reason or act.
6. Render the working set
Use stable sections, clear labels, explicit boundaries, and structured output requirements. A context item should have a reason to be present. The renderer should be versioned so a behavior change can be traced to a change in the assembled input.
7. Trace and evaluate
Record what candidates were considered, what was selected, what was omitted, which policy decisions applied, the exact model-facing context or a privacy-safe equivalent, the model proposal, tool calls, observations, and final outcome. Evaluation must test context assembly as well as the final answer.
The application should make context assembly explicit, bounded, and observable before the model proposes its next step.
This design makes an important separation visible:
authoritative systems
  -> candidate context
  -> model-facing projection
  -> model proposal
  -> deterministic validation and execution
  -> observed outcome
The projection may be incomplete. It may contain uncertainty. It may need to be rebuilt. None of those properties grant the model authority to make an unvalidated change.
A Concrete Example
Consider an incident-triage assistant asked:
Why did the checkout service’s 5xx rate increase after the last deployment, and what should we do next?
A weak implementation might place a runbook, a large log export, a deployment record, and the full conversation into one long prompt. The response may sound plausible, but nobody can tell which evidence was selected, whether the logs were in scope, or whether the recommended action is authorized.
A context-engineered implementation builds the working set in stages.
Initial context
The first model turn receives:
- the user’s goal and requested output;
- the user’s identity, team, environment, and read-only scope;
- the current service and deployment identifiers;
- a concise runbook section for elevated 5xx errors;
- a metrics summary with time range, baseline, and freshness;
- read-only tool definitions for deployment, logs, dependencies, and metrics;
- an explicit instruction that tool outputs are evidence, not policy;
- an output contract requiring hypotheses, supporting evidence, uncertainty, and next diagnostic step.
It does not receive every log line or every document that mentions checkout.
Progressive disclosure
The model proposes a read-only query for errors in the deployment window. The runtime validates the service scope, time range, query cost, and data classification before execution.
The tool returns a compact result:
- query identifier;
- time range and scope;
- error-group counts;
- representative trace identifiers;
- source and freshness;
- a pointer for retrieving full details.
The result is added to the next context. If the model needs more detail, it can request specific traces rather than forcing the entire log stream into working memory.
Decision and action boundary
The model may identify a likely regression and propose rollback or traffic mitigation. It does not execute that action merely because the proposal is coherent. A deterministic policy checks whether the service, environment, change window, and approval requirements permit the action. A human may need to approve it. The runtime records the proposal, evidence, policy decision, execution result, and final state.
The same pattern applies outside incident response. A compliance analyst, researcher, support agent, or internal knowledge assistant also needs a context projection that is relevant, scoped, attributable, and safe to act upon.
Context is a projection of a larger system state, rebuilt and evaluated as the work progresses.
Failure Modes
Context overload or omission
Too much context hides the governing constraint; too little drops the policy or dependency that changes the answer. Optimize for decision relevance, not volume.
Stale, contradictory, or misclassified context
Sources disagree or an evidence item appears to have authority it does not possess. Preserve provenance, freshness, and an explicit trust hierarchy.
Indirect prompt injection
A document, webpage, email, or tool result contains instructions that redirect the model. Constrain what the manipulated model can access and do.
Context drift and silent truncation
Tools, policies, indexes, templates, or limits change, or the runtime silently drops part of the working set. Version and trace the assembled context.
False memory and cost spiral
A prior inference is treated as fact, or repeated history and broad tool definitions drive cost and latency higher. Store memory with source and scope, and bound the working set.
Sources
- Effective context engineering for AI agents, Anthropic: context as the curated set of tokens available to an agent, including instructions, tools, history, and external data; context rot; just-in-time retrieval; compaction; and progressive disclosure.
- Writing effective tools for AI agents, Anthropic: tool descriptions, token-efficient results, clear boundaries, and the relationship between deterministic tools and nondeterministic agents.
- Introducing Contextual Retrieval, Anthropic: the effect of preserving context around retrieved chunks and the importance of retrieval quality beneath RAG systems.
- Harness engineering, OpenAI: repository maps, context scarcity, stale guidance, and the need to make agent environments legible and enforceable.
- From model to agent: Equipping the Responses API with a computer environment, OpenAI: context growth, intermediate state, tool use, execution environments, and the operational problems of longer workflows.
- Designing AI agents to resist prompt injection, OpenAI: prompt injection as manipulation through external content and the need to constrain impact through system design.
- Lost in the Middle: How Language Models Use Long Contexts: research on how language models use information placed at different positions in long contexts.
Subscribe
Get new posts by email
Enterprise architecture, AI systems, and platform strategy.