Deep Research
Deep research turns retrieval into an evidence-producing workflow that plans an investigation, inspects sources, tracks provenance, and synthesizes a report under explicit limits.
Deep Research
When Search Became Knowledge Work
A search engine helps you find possible sources. A research process has to decide what the question means, which sources deserve attention, what each source supports, where evidence conflicts, and when the result is good enough to hand to someone else.
That difference is the reason the phrase deep research has appeared around a new class of model-mediated systems. These systems do more than retrieve pages and write a summary. They plan an investigation, perform several rounds of discovery and inspection, keep track of evidence, and produce a cited report.
The phrase is also being used as a product label. That makes it easy to confuse a vendor’s implementation with the underlying architecture. The durable pattern is not a particular model, browser, or report format. It is a bounded workflow that turns an open question into an evidence-backed artifact while preserving the path between source, claim, and conclusion.
This is Post 10 in The Abstraction Shift: How Software Keeps Moving Up.
Why This Exists
Many questions are not lookups. They are small investigations disguised as prompts.
An architecture team may ask whether a new protocol is suitable for a regulated environment. A product group may want to compare competing approaches across cost, adoption, security, and migration effort. An incident team may need to reconstruct a timeline from logs, tickets, documentation, and deployment history. A researcher may need to compare findings across a literature corpus whose terminology varies between disciplines.
Each question contains several hidden tasks:
- define the decision or outcome;
- clarify scope, time period, audience, and constraints;
- decompose the question into subquestions;
- discover candidate sources;
- prioritize authoritative and diverse evidence;
- inspect sources rather than trusting snippets;
- extract claims, numbers, definitions, and counterexamples;
- identify gaps, conflicts, and stale material;
- synthesize an answer with citations and limitations;
- decide whether the result is complete enough for its purpose.
One-shot generation skips most of this work. One-shot search returns much of the work to the human. Deep research attempts to make the process itself executable.
The need becomes more visible as the source boundary expands. A research system may combine the public web with uploaded documents, internal knowledge bases, databases, structured APIs, or analysis tools. The retrieval technology changes at each boundary, but the research problem remains: which evidence is relevant, authoritative, current, permitted, and sufficient for the claim being made?
What We Did Before
Deep research recomposes several old disciplines. Seeing that lineage keeps the new term from sounding more mysterious than the engineering actually is.
Desk research and analyst work
An analyst starts with an information need, finds sources, records notes, compares claims, and produces a briefing. The work is not just reading. It includes deciding what to investigate next and keeping the evidence organized enough that another person can challenge the conclusion.
The analyst’s notebook, source list, evidence table, and final memo are separate artifacts with different purposes. A research system needs similar distinctions. A source is not an extracted claim. A claim is not a conclusion. A conclusion is not a decision.
Literature and systematic reviews
Literature reviews make search strategy, inclusion criteria, source quality, and synthesis explicit. Systematic reviews add a protocol for how studies are found, screened, and compared. The process is slower than asking for a summary, but it creates a more inspectable relationship between the question and the result.
Deep research does not make those disciplines obsolete. It increases the need for them because an automated system can search and summarize at a scale that makes unsupported completeness easy to imply.
Search engines and information retrieval
Search engines already handle crawling, indexing, ranking, query expansion, spelling correction, and result presentation. They are optimized to help a person find relevant material quickly.
Research asks for a broader contract. It needs to retain the search path, inspect the underlying pages, compare sources, and construct an answer in which each important claim has appropriate support. Ranking is one component of that workflow, not its completion condition.
ETL and data integration
Data pipelines extract records from sources, transform them into a common representation, and load them into a system where they can be analyzed. A research workflow also extracts and transforms, but its inputs are often unstructured and its target representation includes claims, evidence, uncertainty, and interpretation.
The analogy is useful because it highlights a durable distinction: derived data should retain lineage. A polished report without source relationships is like a materialized view with no path back to the records from which it was computed.
Workflow orchestration and review gates
Workflow engines divide work into steps, run tasks, retry failures, persist state, and wait for approvals. Research can use the same machinery for long-running jobs, parallel source retrieval, cancellation, and human review.
The difference is that some transitions are model-mediated. The system may not know every next query in advance. That flexibility belongs inside a bounded workflow, not outside one.
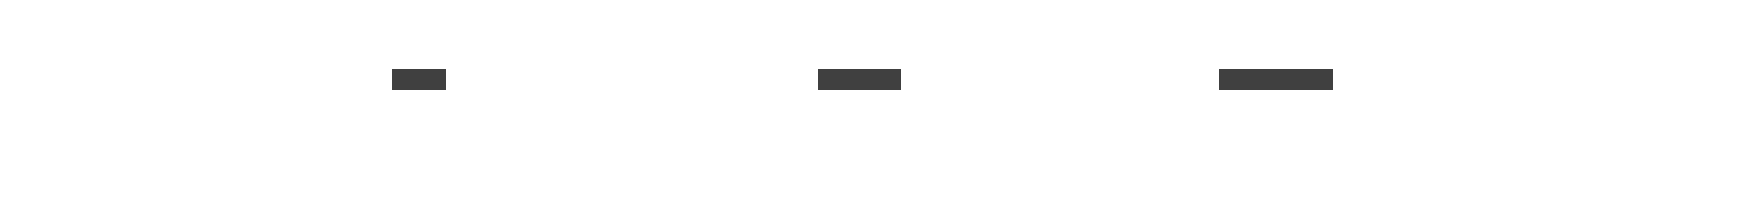
Deep research composes retrieval, model-mediated control, evidence state, and report production into one workflow.
Is It a Search Engine, a RAG System, or an Agent?
The answer depends on which boundary you are looking at.
| System | Primary output | Main control question | Typical stopping condition |
|---|---|---|---|
| Search engine | ranked sources or snippets | which results are relevant to this query? | return a result page |
| RAG pipeline | grounded model response | which context should enter this invocation? | context assembled and response generated |
| Agentic retrieval | improved evidence set | what should be searched or inspected next? | loop budget or evidence condition |
| Deep research workflow | cited research artifact | what must be investigated before synthesis is released? | coverage, budget, review, or explicit uncertainty |
This is a difference in emphasis, not a set of mutually exclusive products. The same application can call a search service, retrieve internal chunks, ask a model to plan the next step, and produce a research report.
The important architectural question is what state survives each step. A RAG call may only need a ranked context window. A deep research workflow needs a research state that can represent the question, subquestions, sources, extracted evidence, unresolved gaps, conflicts, decisions, and report versions.
What’s Actually New?
The research plan becomes executable state
A conventional research plan is often a human note. In a deep research workflow, it can become structured state with subquestions, source policies, priorities, dependencies, and completion criteria.
The model can propose a plan because it is useful at recognizing that a question has several dimensions. The runtime should validate the plan against the task scope and budget. It should also permit a person to edit or narrow it when the research could affect a consequential decision.
An explicit plan makes an important failure visible. If a report skipped security, migration, or counterevidence, the system can show that the dimension was never investigated rather than hide the omission inside fluent prose.
Search becomes a sequence of information-gathering decisions
A single query is often a poor representation of an open question. The system may need a broad discovery query, a primary-source query, a query for criticism or failure, and a query that resolves a terminology mismatch.
The model can generate these queries and adapt them from what it finds. That is the control-flow shift explored in Timed Multi-Round Web Lookup. Deep research adds a stronger emphasis on the resulting artifact and on whether the investigation covered the dimensions that matter.
Evidence becomes more structured than retrieved text
Retrieved pages are too coarse to serve as the only research state. The system needs to know which excerpt supports which claim, whether the source is primary or secondary, when it was published or retrieved, which scope it covers, and whether another source contradicts it.
A useful evidence record may include:
- source identity and retrieval time;
- source type, authority, and access scope;
- excerpt, table, figure, or structured value;
- normalized claim supported by that evidence;
- claim status, such as supported, disputed, inferred, or unresolved;
- relevant date, geography, population, version, or environment;
- relationship to other evidence and known conflicts;
- citation location in the generated report.
This is closer to a claim graph or evidence ledger than to a prompt containing a pile of documents.
Synthesis becomes a derived data product
The final report is a transformation of sources and evidence. It is not a source itself, even when it is well written. Its statements can be direct observations, source-grounded paraphrases, cross-source comparisons, calculations, or the system’s own interpretation.
Those categories should not be collapsed. A sentence that says three vendors publish different authentication models is different from a sentence that recommends one of them for a specific organization. The first can be supported by source comparison. The second also depends on local constraints, risk tolerance, and decision ownership.
Treating the report as a derived product encourages versioning, provenance, regeneration, correction, and review. It also makes it possible to compare two research runs and ask what changed in the evidence rather than only comparing two blocks of prose.
The workflow can cross source boundaries
Deep research may combine the public web, private files, APIs, databases, and analysis environments. That makes the system more useful, but it also creates several authority and privacy domains inside one run.
A public announcement may establish that a capability exists. An internal incident record may establish whether it works in a particular environment. A spreadsheet may contain the organization’s cost assumptions. The report should preserve those distinctions rather than present all inputs as equally authoritative.
Completeness becomes a policy claim
No open-web investigation can establish that it found everything relevant. A research workflow can establish that it met a declared protocol: it searched the allowed sources, covered the planned subquestions, inspected the required primary documents, and stopped within its budget.
That is a more honest definition of completion. “Complete” should mean complete enough for a stated purpose and protocol, not universally exhaustive.
Where the Analogy Breaks
Deep research benefits from the analogy to analysts and systematic reviews, but model-mediated execution introduces breaks that need explicit controls.
More sources do not guarantee better coverage
The system may collect dozens of pages that all repeat one announcement. Source count is a weak measure of evidence diversity. A good investigation may need fewer sources, but from different roles: a specification, an implementation, an independent evaluation, a failure report, and the local system of record.
Coverage should be measured against the claims and subquestions that matter, not the number of URLs opened.
A citation does not prove support
A report can include a real citation that does not support the sentence next to it. The source may discuss a narrower population, an older version, or a different claim. A generated citation can also point to a page that was never inspected closely enough.
Citation correctness is a separate check from citation presence. The system should preserve a relationship between claim and evidence and, where possible, verify that the cited passage supports the wording and scope of the claim.
Authority is contextual
An official source is authoritative about what an organization publishes. It is not automatically authoritative about whether the product works in every environment, whether an implementation is secure, or whether a recommendation fits a particular organization.
Source authority should be evaluated against the claim. The right evidence for a protocol’s syntax may be the specification. The right evidence for operational reliability may include independent tests, incident history, and local observations.
Web content is evidence, not instruction
Pages, documents, and tool results can contain text that tries to redirect the model. Research systems must treat retrieved content as untrusted data and keep it separate from the instructions that govern the research runtime. This is a prompt-injection problem at the evidence boundary.
The system needs source handling, content isolation, tool permissions, and output checks. A page should be able to contribute a claim without acquiring authority over what the research agent does next.
Synthesis can hide disagreement
A fluent paragraph often compresses disagreement into a smooth average. That may be useful for a high-level briefing, but it can conceal that sources use different definitions, measure different periods, or reach conflicting results.
The report should preserve material conflicts and explain why one source was weighted differently. Uncertainty is part of the artifact, not an editing defect to remove.
Open-ended research has no universal stopping proof
There is rarely a final test that proves a research question has no additional relevant evidence. A system can stop because it met its protocol, exhausted its budget, reached diminishing returns, or requires a human judgment.
These states should be distinct. A timeout is not the same as sufficient evidence. A report that says “research stopped after the source and time limits were reached” is more useful than one that implies exhaustive certainty.
A report is not a decision
Research can make a decision easier without making it automatically. The final recommendation may depend on values, risk appetite, legal interpretation, organizational capacity, or information unavailable to the research system.
The report should expose evidence and reasoning for a decision owner. It should not silently convert a model-generated synthesis into an authorized policy, purchase, deployment, or customer commitment.
Under the Hood
The research loop is best implemented as a workflow with a model inside it, not as an unbounded prompt that happens to call search.
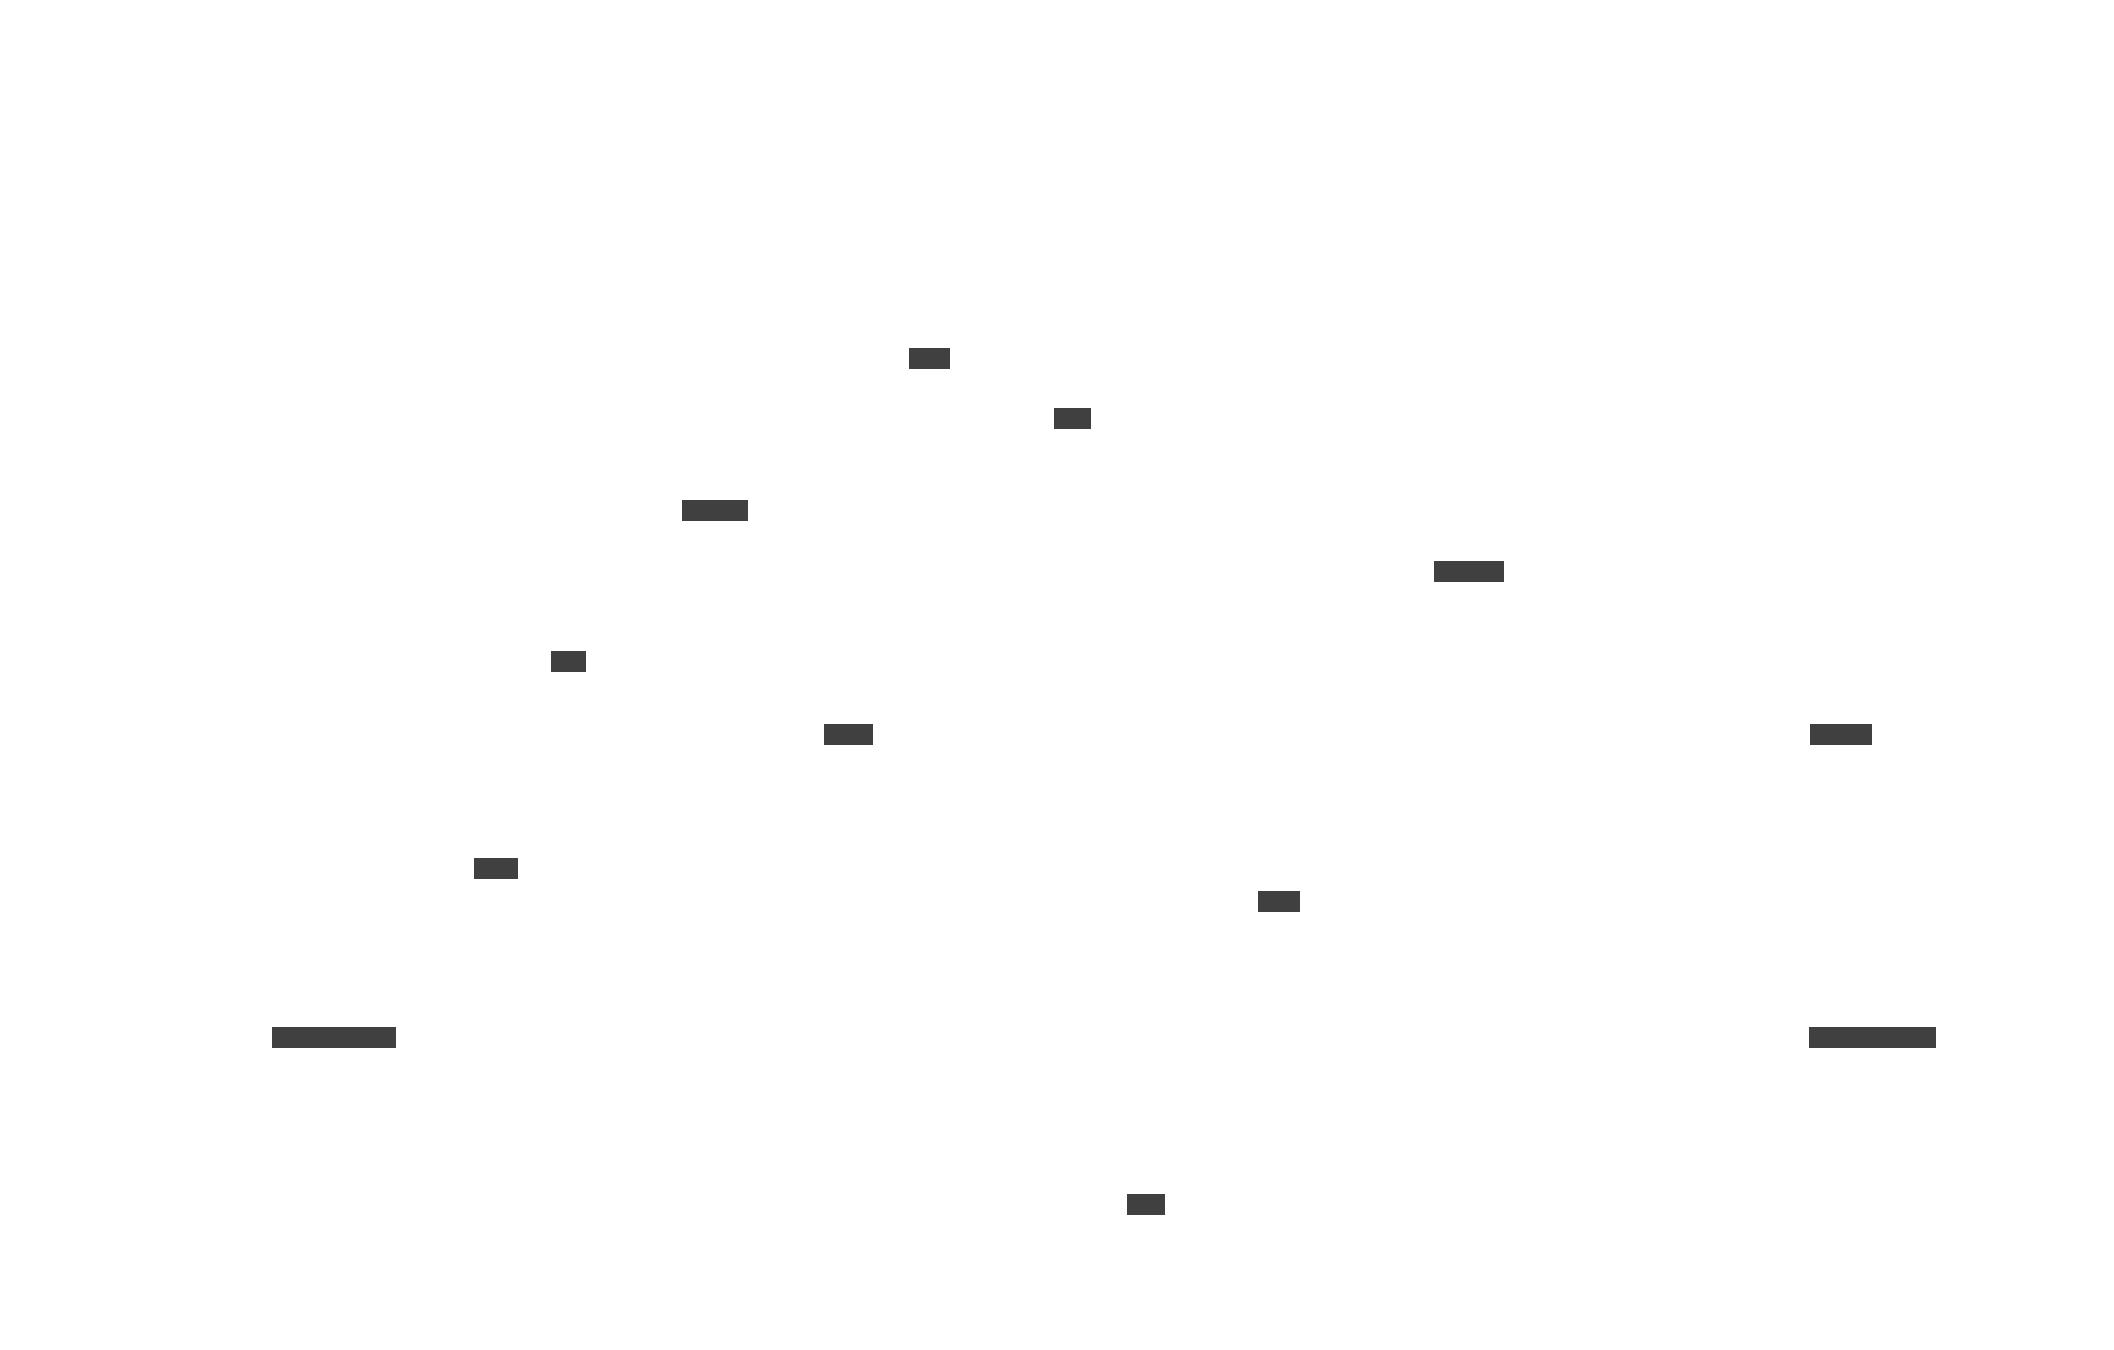
The model can propose research moves, but the runtime controls scope, source access, budgets, provenance, and release.
1. Define the outcome and research contract
Start with the decision, audience, scope, time horizon, source boundary, and required report shape. Ask what the report must help someone do. A market landscape, an incident timeline, and a protocol adoption recommendation need different evidence and stopping rules.
The contract should state what is out of scope, which sources are allowed, whether private data may be used, how fresh the evidence must be, and which claims require human review.
2. Plan the investigation
Generate subquestions and an initial source strategy. Include queries for definitions, primary evidence, alternatives, counterevidence, operational constraints, and recent changes where they matter.
The plan should be editable and observable. If the model changes the plan, record the reason and the evidence that caused the change. A plan is not a promise that every branch will be explored. It is a way to make the intended coverage explicit.
3. Discover candidate sources
Use search, repositories, connectors, APIs, and uploaded material to find candidate sources. Keep discovery separate from source acceptance. A search result, snippet, or generated reference is a lead until the underlying source is inspected.
Deduplicate sources, record retrieval time, and apply identity, tenant, licensing, and access controls before the content enters the working set.
4. Inspect and extract evidence
Open the source and extract the passages, tables, figures, or structured values relevant to a subquestion. Normalize them into claims without losing the source’s scope, date, version, and qualifications.
The model is valuable here because it can interpret varied formats and identify relationships across documents. Deterministic code should preserve identifiers, timestamps, permissions, and original content where those fields matter.
5. Maintain an evidence ledger
Record what supports each claim, what contradicts it, which questions remain open, and how much of the budget the run has used. The ledger should be queryable by subquestion and claim, not only by source.
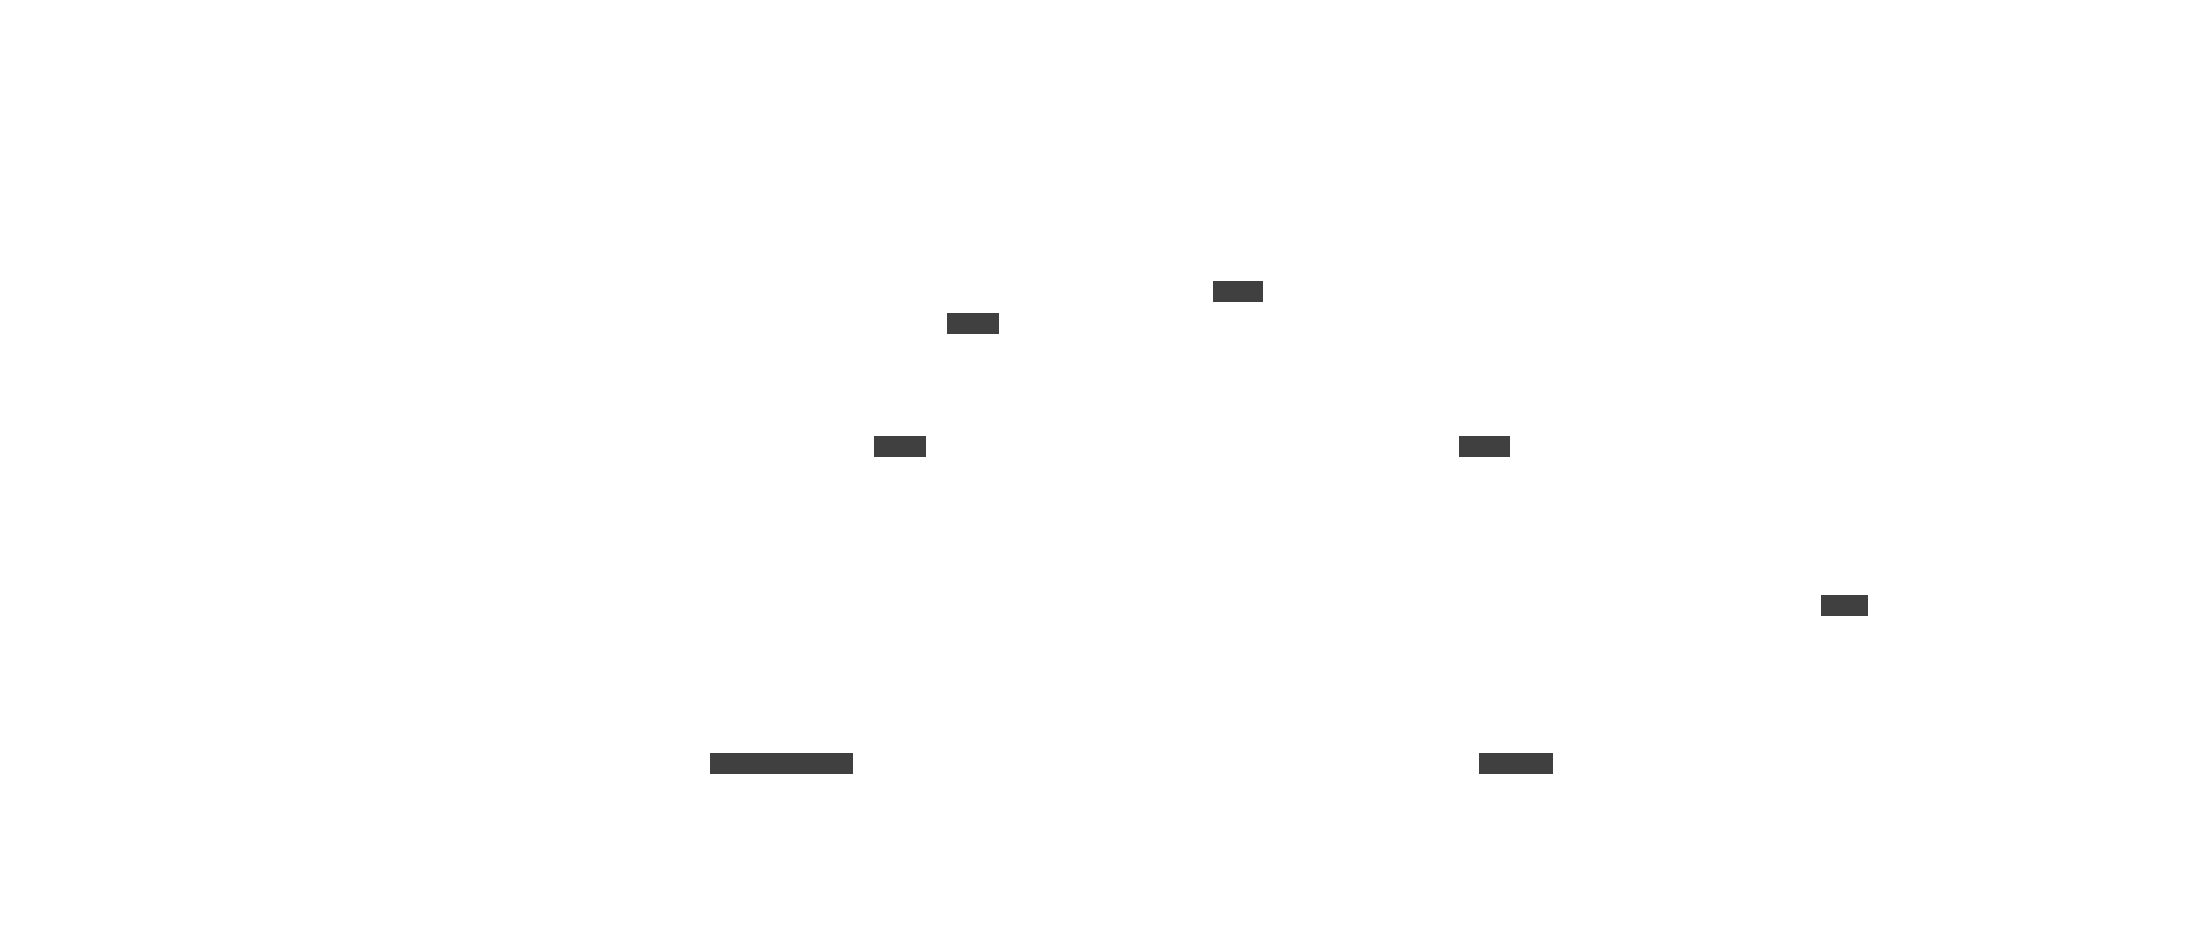
A report is a derived artifact. Its claims should remain traceable to sources, while the decision remains a separate responsibility.
6. Search for gaps and counterevidence
Use the current evidence state to decide what is missing. A good next query may challenge the working conclusion, find a newer version, inspect a primary document, or test whether two sources are actually comparable.
This step is where deep research can outperform a linear summary. It can ask what would change the conclusion, then look for that evidence. Without an explicit counterevidence step, the loop may simply elaborate its first hypothesis.
7. Synthesize with claim-level citations
Generate the report from the evidence ledger and the research contract. Keep claims close to their citations, preserve material uncertainty, and separate sourced statements from comparisons, calculations, and recommendations.
The synthesis stage should not be allowed to invent support after the ledger is complete. If a sentence cannot be traced to evidence or clearly labeled as interpretation, it should be revised, removed, or marked unresolved.
8. Review and stop with a reason
The runtime should decide whether to release, revise, ask for clarification, or escalate. It can use coverage thresholds, source requirements, citation checks, budget limits, freshness rules, or human approval.
Useful stop states include:
- sufficient evidence under the declared protocol;
- sufficient for a low-risk orientation, but not for a decision;
- unresolved conflict requiring human review;
- budget or time exhausted;
- source access or freshness constraint reached;
- report generated with explicit limitations.
The stop reason belongs in the trace and, when useful, in the report.
A Concrete Example
Suppose an enterprise architecture group asks:
Should we adopt a shared capability-discovery protocol for internal AI applications over the next year?
A shallow system might search for the protocol name, summarize the official documentation, and recommend adoption. A deep research workflow should make the decision surface explicit.
Frame the question
The report contract names the intended consumers, existing integration patterns, regulated data boundaries, required authentication model, supported transports, expected scale, migration horizon, and decision audience. It also says that the report is an assessment, not an approval to deploy.
Build the research plan
The plan includes:
- what problem the protocol solves compared with existing APIs and adapters;
- how capability discovery, invocation, identity, and authorization are represented;
- how versioning, errors, timeouts, and observability work;
- what implementations and ecosystem support actually exist;
- what security and prompt-injection risks cross the boundary;
- what migration and operating costs the organization would incur;
- which claims remain uncertain or depend on local testing.
Gather and compare evidence
The workflow inspects the current specification and security documentation, implementation repositories, independent technical evaluations, relevant incident reports, and the organization’s own integration inventory. It records where the official contract is clear and where real implementations diverge.
The evidence ledger may show that the protocol improves capability discovery but does not solve authorization. It may show that transport support is broad while operational tooling is immature. It may also reveal that an existing internal gateway already provides some of the needed governance.
Produce the artifact
The report contains a decision summary, architecture comparison, security assessment, migration options, cost and operating implications, evidence table, unresolved questions, and a proposed pilot. Each important claim points to a source or local record. The recommendation is conditional on the local pilot and security review.
The same workflow applies to vendor due diligence, compliance research, literature surveys, incident reconstruction, policy analysis, and internal technical investigations. The sources differ. The durable pattern is the same: a bounded investigation produces a traceable artifact for a human or an application to use.
Failure Modes
Incomplete or biased coverage
More sources do not prove completeness. Define the research scope, search for gaps and counterevidence, and state what remains unknown.
Citation without support
A citation can exist without supporting the attached claim. Keep claim-level provenance and inspect the cited passage.
Authority and instruction confusion
Web content is evidence, not authority. Preserve source status and resist instructions embedded in retrieved material.
Hidden disagreement
Synthesis can flatten conflicts between sources. Keep disagreement visible and explain which source governs the conclusion.
Unbounded research
Open-ended investigation can consume time and budget without improving the decision. Set stopping conditions and report the evidence limit.
Report mistaken for decision
A well-supported report still requires an accountable decision owner. Separate evidence production from the action it informs.
Sources
- Introducing deep research, OpenAI: describes a model-mediated system that plans multi-step web research, uses tools, pivots as it encounters new information, and produces documented reports.
- Deep research in ChatGPT, OpenAI Help Center: documents the current user-facing research flow, including proposed plans, source controls, progress, interruption, and cited reports.
- Building effective agents, Anthropic: distinguishes predefined workflows from systems in which models dynamically direct tool use and discusses research-agent architecture patterns.
- Deep Research: A Survey of Autonomous Research Agents: surveys planning, question development, web exploration, and report generation as components of autonomous research systems.
- DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents: proposes evaluation methods for report quality, effective citation count, and citation accuracy.
- SAGE: Benchmarking and Improving Retrieval for Deep Research Agents: examines reasoning-intensive retrieval and shows why the research agent’s search behavior remains an information-retrieval problem.
Subscribe
Get new posts by email
Enterprise architecture, AI systems, and platform strategy.