Timed Multi-Round Web Lookup
Web search is turning into a bounded, multi-round loop where a model helps choose what to search next and when to stop, and that loop deserves the same architectural discipline as any other production system.
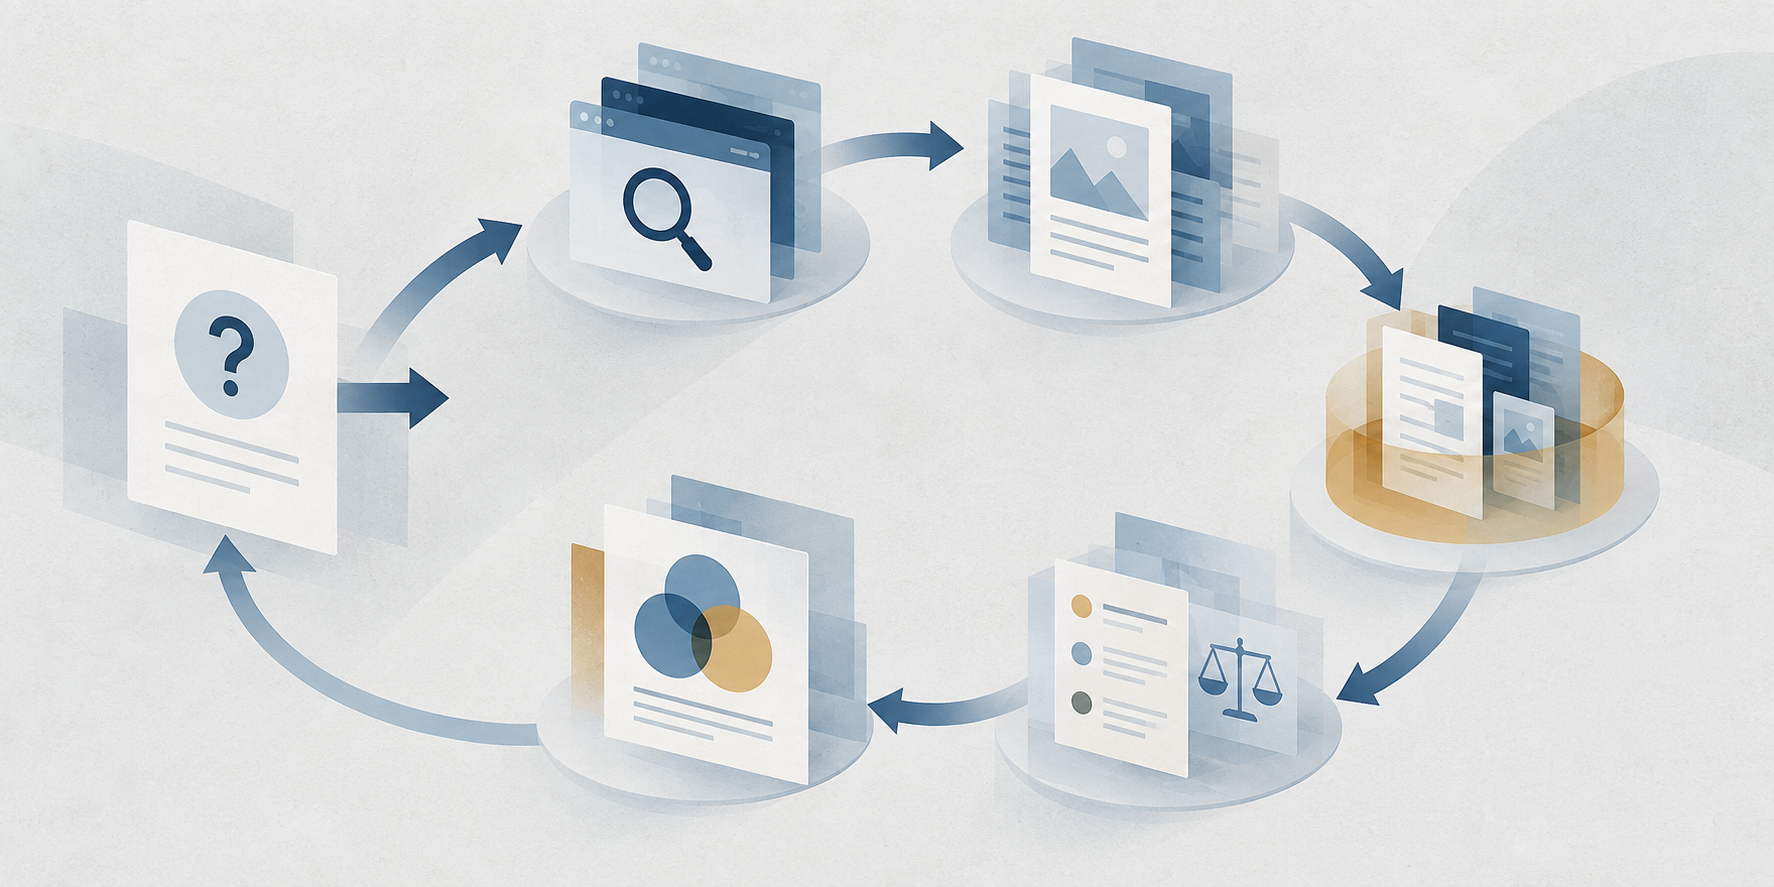
When Search Became a Loop
The useful shift is not that software can search the web. It is that a model can help decide what to search next, what evidence to retain, and when the research is good enough to stop.
This is Post 01 in The Abstraction Shift: How Software Keeps Moving Up.
Why This Exists
A single search query works well when the question is narrow and the answer is already well indexed. It becomes less useful when the question has several parts, when the relevant terminology is uncertain, or when the answer depends on comparing sources rather than finding one page.
Research questions usually require a sequence:
- understand the question;
- identify the subquestions;
- find likely sources;
- inspect those sources rather than trusting snippets;
- identify gaps or contradictions;
- search again with better queries;
- decide whether the evidence is sufficient;
- produce a synthesis that preserves provenance.
Research has always been iterative. What is changing is the possibility of placing a model inside the loop and allowing it to choose some of the next moves.
The word “timed” matters less as a label than as a design constraint. Open-ended research is not a usable production contract. A system needs limits on elapsed time, number of searches, context growth, tool calls, and sometimes financial cost. A research agent without a stopping policy is simply an expensive process that has not finished yet.
What We Did Before
The lineage is not difficult to find.
Search engines turned information retrieval into a service. Query planning, query expansion, ranking, crawling, indexing, and relevance feedback all addressed parts of the problem before anyone called the system an agent.
RAG then made retrieval an explicit part of an application pipeline: retrieve relevant material, place it in context, and generate a response grounded in that material.
Workflow engines added another familiar idea: a task can move through stages, retry failed work, run steps in parallel, and stop when a defined condition is met.
The older systems already contained search, iteration, ranking, state, and control flow. The current shift composes those capabilities around a model that can help decide how the loop proceeds.

The new pattern composes familiar retrieval and workflow ideas around model-mediated decisions.
What’s Actually New?
Four changes are worth separating.
1. The model can influence the next query
The system may use the question, previous results, and unresolved gaps to generate another search query. It can move from a broad query to a more specific one, search for a primary source, or look for evidence that challenges an early conclusion.
2. Evidence becomes working state
The system needs more than a pile of retrieved text. It needs to retain sources, claims, provenance, confidence, contradictions, and questions still unresolved. That is a context and state problem, not just a retrieval problem.
3. Time and execution budgets become architectural inputs
The outer system must decide how much time, context, money, and tool access the research is allowed to consume. These limits shape the answer and should be visible in evaluation.
4. Stopping becomes part of quality
The system has to decide whether another round is likely to improve the answer. Stopping too early produces a shallow answer, and continuing too long produces cost, latency, duplication, and sometimes a false sense of confidence.
Where the Analogy Breaks
It is tempting to call this “search with a loop.” That is directionally correct, but incomplete in several places.
Traditional search optimizes retrieval and ranking against an information need. A multi-round research system is also managing a goal, a plan, a working evidence set, and a response. The quality of the final result depends on the sequence of decisions, not just the relevance of one result page.
A workflow loop follows logic that engineers define in advance. A model-mediated loop may choose a different query, source, or stopping point for the same initial request. It can be flexible, but that flexibility is a source of nondeterminism.
RAG usually describes how information is retrieved and supplied to a model. Multi-round lookup describes a broader control pattern in which retrieval can be invoked, evaluated, and repeated as part of the application’s reasoning process. A system can use RAG inside the loop without RAG itself becoming agentic.
The analogy breaks most clearly when the research system is allowed to act on weak evidence. Search results are not facts, and snippets are not sources: a citation does not prove that the cited page supports the sentence attached to it.
Under the Hood
A production-oriented design separates the model’s judgment from the controls that protect the system. The research-loop diagram below makes that boundary explicit:
The model may propose the next action. The deterministic boundary should still enforce permissions, budgets, timeouts, deduplication, provenance requirements, and stopping rules.
The model can help choose the next research move, but the outer system should control the budget and the boundaries.
A useful event trace records at least:
- the initial goal and constraints;
- each query and the reason it was selected;
- sources opened and evidence retained;
- claims accepted, rejected, or left unresolved;
- time, token, and tool-call consumption;
- the stopping decision;
- the final claims and their supporting sources.
Without this trace, debugging becomes a conversation transcript review. That is rarely enough for a system expected to operate repeatedly or at enterprise scale.
The evidence ledger preserves what the system found, why it trusted it, and what still needs attention.
A Concrete Example
Suppose an architecture team asks:
Should we adopt a new protocol for connecting AI applications to enterprise tools?
A reasonable three-round research run might look like this:
Round 1: establish the landscape
Search for the protocol specification, official announcements, implementation examples, and competing approaches. The goal is breadth and vocabulary, not a final recommendation.
Round 2: inspect the important sources
Open the primary specification and documentation. Search specifically for security, authentication, versioning, error handling, capability discovery, and operational limits. The system should record what the sources actually say rather than relying on search snippets.
Round 3: test the decision
Look for gaps and counterevidence. Does the protocol solve a real integration problem? What would adoption require in identity, governance, monitoring, and support? If the evidence is still weak, the system should say so or request human review rather than manufacture certainty.
The output is not merely a list of links; it is a bounded synthesis with a record of how the answer was formed.
The same pattern applies to compliance reviews, literature reviews, incident analysis, vendor due diligence, and research over an internal document corpus. The source boundary changes, but evidence quality, permissions, and stopping policy remain part of the design.
Failure Modes
- Premature or endless stopping: stop too early and gaps remain; continue too long and cost rises without improving the answer.
- Confirmation search: follow-up queries reinforce the first hypothesis instead of testing it.
- Source and evidence drift: secondary, stale, duplicated, or weak sources are mistaken for independent support.
- Evidence contamination: retrieved content contains instructions that influence behavior rather than serving as evidence.
- Citation mismatch: the final citation does not support the claim attached to it.
- Invisible uncertainty: a partial synthesis is presented as complete.
Budgets, provenance, source identity, and explicit stopping reasons keep a research loop inspectable.
Sources
- Web search, OpenAI API: a current reference for extending model responses with web search and source citations.
- Building effective agents, Anthropic: a useful distinction between predefined workflows and systems where models dynamically direct tool use.
- From Web Search towards Agentic Deep Research: Incentivizing Search with Reasoning Agents: research on the progression from conventional web search toward iterative retrieval and synthesis.
- Model Context Protocol specification: a current reference for discovering and invoking tools from model-connected applications.
Subscribe
Get new posts by email
Enterprise architecture, AI systems, and platform strategy.